---
license: apache-2.0
language:
- en
- zh
base_model:
- Efficient-Large-Model/Sana_600M_1024px_diffusers
pipeline_tag: image-to-image
tags:
- image-compression
- dit_ic
- diffusion_transformer
datasets:
- Whiteboat/MLIC-Train-100K
---


# 🐱 DiT-IC Model Card
Source code is available at [Github](https://github.com/Eric-qi/DiT-IC).
## Model Description
- **Developed by:** NJU VisionLab
- **Model type:** Diffusion Transformer based image compression model
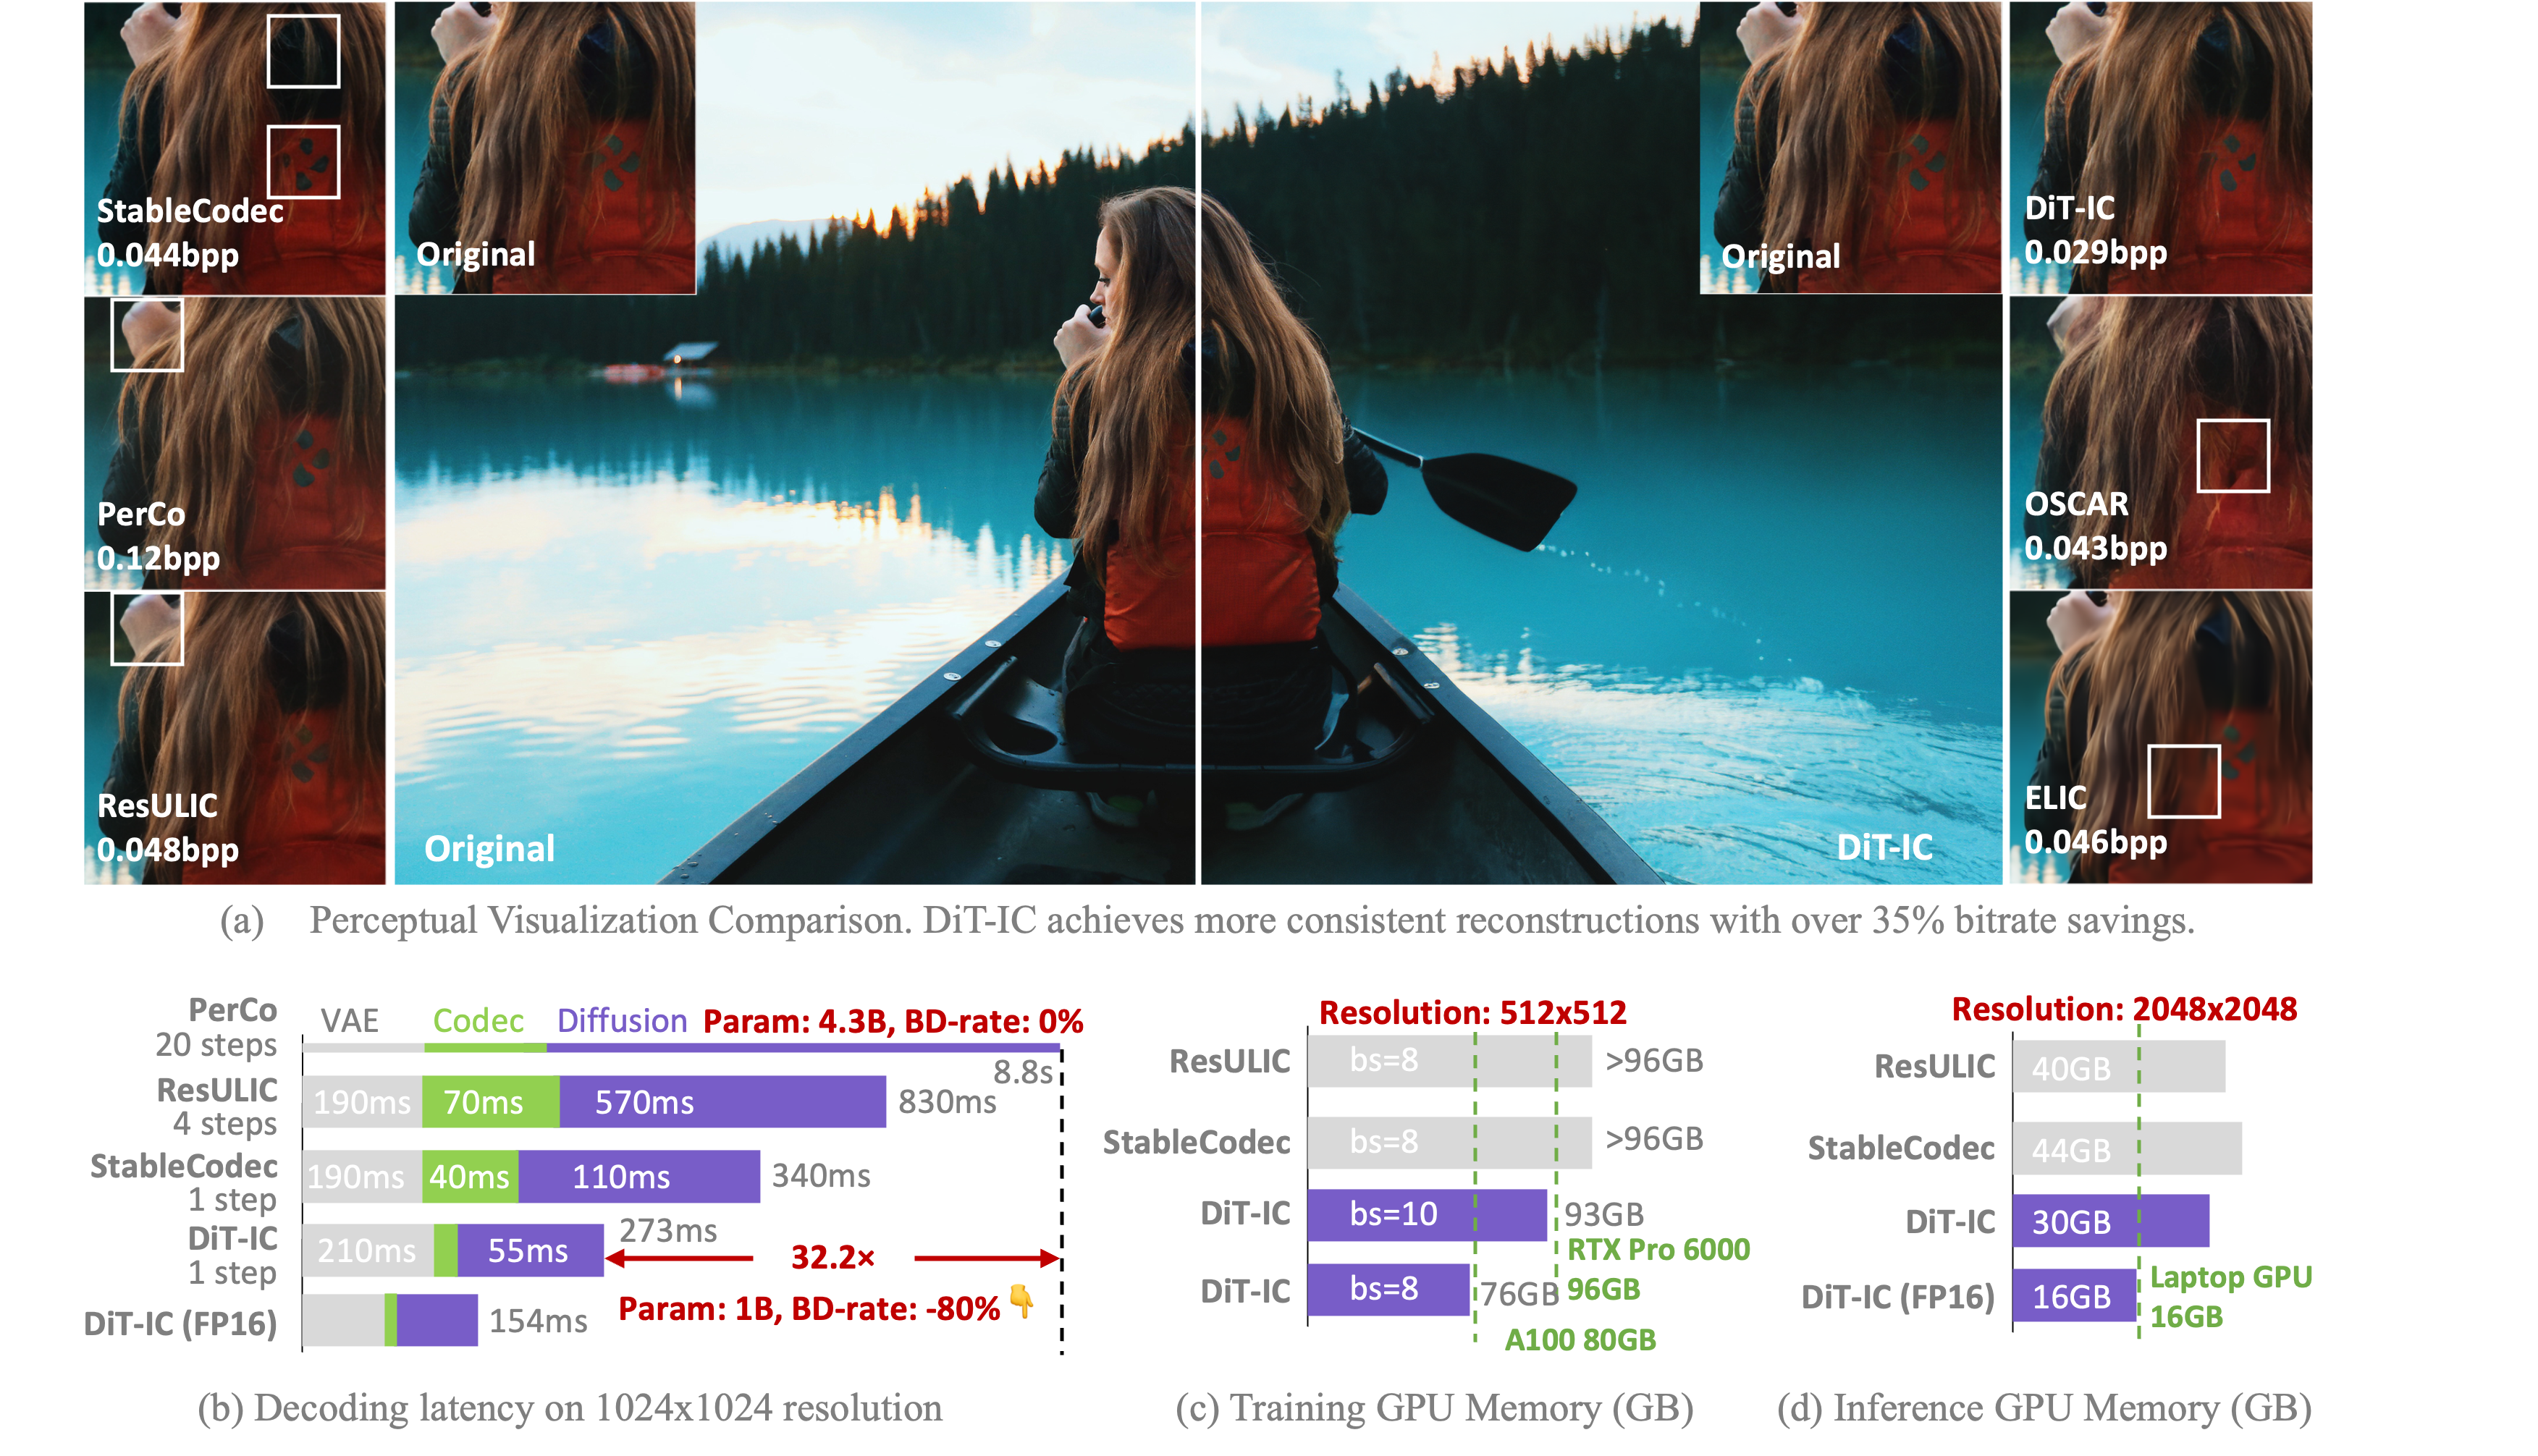
- **Model size:** 1.049 B parameters
- **Resolution:** Supports arbitrary resolution images
This model performs the diffusion process in a 32× latent space to reduce memory usage and accelerate inference.
The model is based on the pretrained text-to-image generative model [SANA-600M](https://huggingface.co/Efficient-Large-Model/Sana_600M_1024px_diffusers).
## Quick Start
For training and inference scripts, please visit our [GitHub Repository](https://github.com/Eric-qi/DiT-IC).
## Limitations
- The model may fail to reconstruct tiny text at low bitrates.
- Fingers and other fine structures may not be generated properly.
## Citation
If you use this model, please cite:
```bibtex
@inproceedings{shi2026ditic,
title={DiT-IC: Aligned Diffusion Transformer for Efficient Image Compression},
author={Shi Junqi, Lu Ming, Li Xingchen, Ke Anle, Zhang Ruiqi and Ma Zhan},
booktitle={CVPR},
year={2026}
}