---
base_model:
- GSAI-ML/LLaDA-8B-Base
base_model_relation: adapter
datasets:
- YanZhanPKU/Entropy-Valley-Datasets
language:
- zh
- en
library_name: peft
license: other
license_name: llada-8b-base-license
license_link: https://huggingface.co/GSAI-ML/LLaDA-8B-Base
pipeline_tag: translation
metrics:
- comet
- bleu
tags:
- entropy-valley
- translation
- machine-translation
- masked-diffusion
- diffusion-language-model
- llada
- lora
- peft
- arxiv:2608.22274
pretty_name: Entropy-Valley-LLaDA-8B-Zh2En
---
Entropy-Valley · LLaDA-8B Chinese→English
Official **Chinese→English** LoRA adapter for [Length-Adaptive Decoding for Masked Diffusion Machine Translation](https://arxiv.org/abs/2608.22274) (EMNLP 2026 Main Conference). It turns [`GSAI-ML/LLaDA-8B-Base`](https://huggingface.co/GSAI-ML/LLaDA-8B-Base) into a masked-diffusion MT system for Zh→En.
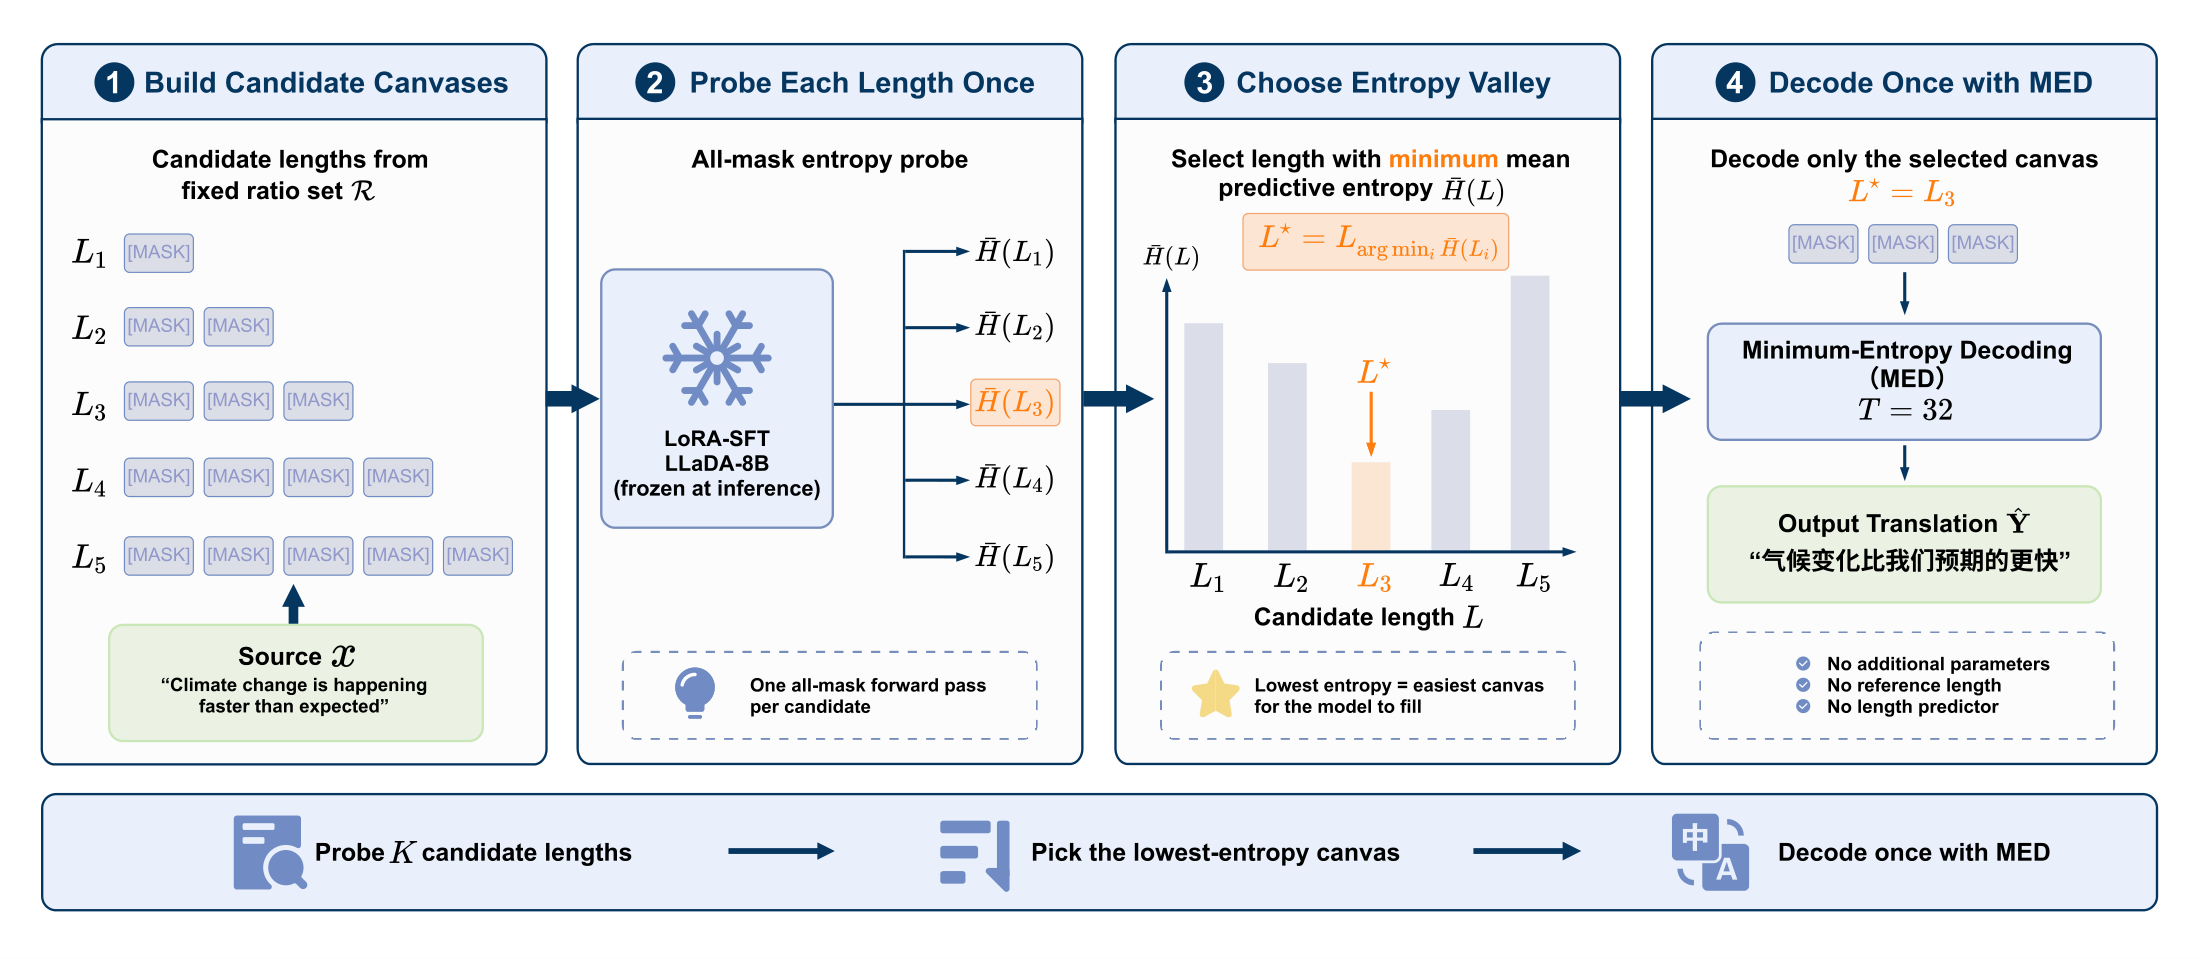
> **The adapter is not the method.** **Entropy-Valley (EV)** is a *training-free, decoding-time* length selector, implemented in [`ladit/decoding/length_adaptive.py`](https://github.com/Entropy-Valley/Entropy-Valley/blob/main/ladit/decoding/length_adaptive.py). This adapter is the fixed backbone that EV decodes with — the same weights serve the length-oracle, fixed-ratio, and EV conditions. Only the canvas length handed to the decoder changes.
## How Entropy-Valley works
A masked diffusion LM fills a **fixed-size canvas**: it must be told how many target slots to produce *before* denoising begins, and there is no autoregressive EOS to stop it. EV asks the frozen backbone which canvas it is most prepared to fill — one all-mask forward pass per candidate length, scored by mean predictive entropy over the first $L-1$ slots (the last is reserved for EOS), then decode the minimum:
$$L^{\star} = \arg\min_{L \in \mathcal{C}(\mathbf{x})} \bar{H}(L), \qquad \bar{H}(L) = \frac{1}{L-1}\sum_{i=1}^{L-1} H\big(p_\theta(y_i \mid \mathbf{x}, \texttt{[MASK]}^L)\big)$$
## Quick facts
| | |
|---|---|
| **Base model** | `GSAI-ML/LLaDA-8B-Base` (8.02B, masked diffusion) |
| **Adapter** | LoRA `r=64`, `α=128`, dropout `0.05` on `q/k/v/o_proj` + `ff_proj/up_proj/ff_out` |
| **Training data** | 200k WMT19 zh-en pairs ([Entropy-Valley-Datasets](https://huggingface.co/datasets/YanZhanPKU/Entropy-Valley-Datasets), config `enzh`, roles swapped), 3 epochs, bf16, 8×H20 |
| **Decoding** | MED schedule, $T{=}32$ steps, EOS truncation |
| **EV candidate grid** | $\mathcal{R} = \{1.00, 1.10, 1.20, 1.30, 1.40\}$, fixed for the direction |
| **Prompt template** | `Translate Chinese to English.\n\nChinese: {src}\nEnglish: ` |
## Results
WMT22 Zh→En ($N{=}2{,}037$), 32-step MED decoding, mean over three independent training runs.
| Length method | COMET-22 | sacreBLEU |
|---|---|---|
| Fixed ratio 1.2 | 0.8266 | 23.65 |
| **Entropy-Valley** | **0.8431** | **25.28** |
| Length oracle † | 0.8519 | 27.93 |
† Decodes at the *reference* target length — an upper bound, not a deployable method. EV closes **65.3%** of the gap between the two.
This is the direction with the strongest human-evaluation support in the paper. Significance tests, the expert study, comparisons against DAEDAL and CAL, cross-backbone results, and all ablations are in the [paper](https://arxiv.org/abs/2608.22274). This repository releases one of the three training runs behind the means above.
## Usage
```bash
git clone https://github.com/Entropy-Valley/Entropy-Valley.git && cd Entropy-Valley
pip install -e .
```
```python
import torch
from transformers import AutoConfig, AutoModelForCausalLM, AutoTokenizer
from peft import PeftModel
from ladit.data.mt_dataset import set_lang_pair
from ladit.decoding.length_adaptive import entropy_valley_probe, set_mask_token_id as set_ev_mask
from ladit.decoding.translate import translate_single, set_mask_token_id as set_dec_mask
BASE, ADAPTER = "GSAI-ML/LLaDA-8B-Base", "YanZhanPKU/Entropy-Valley-LLaDA-8B-Zh2En"
tokenizer = AutoTokenizer.from_pretrained(BASE, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(BASE, trust_remote_code=True,
torch_dtype=torch.bfloat16).to("cuda")
model = PeftModel.from_pretrained(model, ADAPTER).merge_and_unload().eval()
mask_tid = getattr(AutoConfig.from_pretrained(BASE, trust_remote_code=True), "mask_token_id", 126336)
set_ev_mask(mask_tid); set_dec_mask(mask_tid)
set_lang_pair("zh-en")
src = "很抱歉,您点的餐可能会晚到一会。"
n_src = len(tokenizer.encode(src, add_special_tokens=False))
candidates = sorted({max(1, int(n_src * r)) + 1 for r in (1.00, 1.10, 1.20, 1.30, 1.40)})
L_star = entropy_valley_probe(model, tokenizer, src, candidates)["best_length"]
out = translate_single(model, tokenizer, src, target_length=L_star,
num_steps=32, schedule_name="med")
print(L_star, out["translation"])
```
Reproduce the full WMT22 evaluation (decodes all three length methods and scores BLEU + COMET-22):
```bash
python scripts/decode_eval.py \
--model_path /path/to/LLaDA-8B-Base \
--lora_path YanZhanPKU/Entropy-Valley-LLaDA-8B-Zh2En \
--input_file data/wmt22_enzh_test.jsonl \
--output_dir eval_results/zhen_ev \
--num_examples 2037 --num_steps 32 --schedule med \
--methods "oracle,ratio_1.2,entropy_valley" \
--candidate_ratios "1.00,1.10,1.20,1.30,1.40" \
--lang_pair zh-en --device cuda
```
Zh→En reuses `wmt22_enzh_test.jsonl` — `--lang_pair zh-en` swaps which key is source and which is target.
## Limitations
- EV can only choose among the fixed candidate grid. A candidate-width control in the paper shows this direction benefits from a wider window than the deployed default; the grid is kept fixed for protocol consistency.
- The adapter is tied to LLaDA-8B-Base and to WMT-style news/web text; high-risk domains should retain human review.
- EV operates only at inference time and inherits the safety and bias profile of the backbone and the training data.
## Citation
```bibtex
@inproceedings{zhan2026lengthadaptive,
title = {Length-Adaptive Decoding for Masked Diffusion Machine Translation},
author = {Zhan, Yan and Hou, Mengkai and Zhang, Wanting and Gao, Zhijun},
booktitle = {Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP)},
year = {2026},
eprint = {2608.22274},
archivePrefix = {arXiv},
primaryClass = {cs.CL},
url = {https://arxiv.org/abs/2608.22274}
}
```
## License
Adapter weights inherit the [`GSAI-ML/LLaDA-8B-Base`](https://huggingface.co/GSAI-ML/LLaDA-8B-Base) base-model licence. Code is MIT.