


APUS Reflex: Learning to Decide Across Compute Budgets
Technical Report v1.1
gumpcheng (https://huggingface.co/xDAN2099) · zhangxu
APUS AI-LAB
Abstract
Many useful language-model interactions end in a decision: choosing a browser action, applying a principle, routing a workflow, or determining whether evidence supports an attribute. These interactions require language understanding, but their outputs often occupy a small, explicitly defined space. APUS Reflex organizes model computation around that distinction. It combines language-conditioned candidate decisions, jointly trained execution depths, and a text objective for workflow steps that require open responses. A shared model exposes low and high effort modes, connecting application budgets to the depth of neural computation. Cross-depth self-distillation transfers information from the deeper decision distribution into an earlier exit. We describe the delivered training framework, its 4B and 9B instantiations, and Jet-DCRL, a separately implemented research extension for decision utility and probability quality. Development results establish an initial accuracy reference; the evaluation agenda targets the broader relationship between decision quality, execution cost, and workflow outcomes.
Model value
APUS Reflex brings language understanding to the decision points where applications need an actionable choice. Its value comes from combining decision quality, a direct output path, and control over computational effort within one deployable model family.
- Evidence-informed decisions. Tasks, policies, and candidate actions are expressed in natural language, so a shared model can address changing business rules and action spaces. The 9B model achieves 85.00% accuracy on the development comparison panel, alongside 82.50% for the Jev API. Section 7 presents the shared evaluation setting and results.
- Less work between understanding and action. Candidate scoring produces a bounded decision without decoding a complete structured document. This targets the repeated selection steps found in browser agents, business routing, and workflow handoffs.
- Compute that fits the workflow. Jointly trained low and high effort modes let applications choose the execution budget appropriate to each decision point. This creates a practical basis for balancing decision quality with latency and resource cost. In the native low path, candidate-aware projection further limits output-head work to the supplied labels on supported heads, pairing depth control with output-width control while retaining a shared language output space.
- Deployment under application control. Downloadable 4B and 9B weights and an accompanying runtime support local decision execution, giving teams control over infrastructure, data handling, and integration into existing systems.
For browser agents, the target is choosing the next action from page evidence and a goal. For high-frequency business services, it is applying a supplied rule or routing a request to an appropriate next step. For workflow handoffs, it is returning a decision that host code can map into a structured action. These scenarios share the same language-conditioned decision interface; their production value can be evaluated through both decision correctness and completed workflow outcomes.
1. From Text Completion to Language-Conditioned Decisions
The value of a decision model lies in interpreting a changing problem, rather than memorizing a fixed business taxonomy. A browser page presents different elements at every step. A workflow may introduce a new policy, tool, or routing destination. The relevant candidate set therefore belongs to the request itself. APUS Reflex receives the context, question or instruction, and candidate descriptions in language, then returns a decision over that request-specific set.
This representation preserves a central strength of language models: task meaning is communicated through the input. A common model can process evidence-based questions, natural-language principles, workflow states, and browser actions without requiring a separate output classifier for every business category. Compact output labels identify candidates; their meaning comes from the descriptions supplied for the current request. They are an interface to the decision space, not permanent class identities.
For candidates A(x) = {a1, …, aK}, an execution depth d produces logits zd(x, A). The decision distribution is:

Normalization takes place within the legal candidate set. A deterministic application layer can map the selected label into its structured response. This removes the need to generate JSON punctuation or repeatedly decode a known answer schema. It guarantees membership in the supplied candidate set, while semantic correctness remains a learned capability that must be evaluated. Open text is retained where the task genuinely requires it, such as entering a value during a browser workflow.
2. A Shared Model Across Compute Budgets
APUS Reflex makes execution depth an explicit part of the decision framework. The same parameter set supports an earlier decision exit and a deeper exit. Applications select effort="low" or effort="high" according to the latency and quality needs of a workflow. The two modes change the neural computation performed, rather than merely changing a response-length limit.
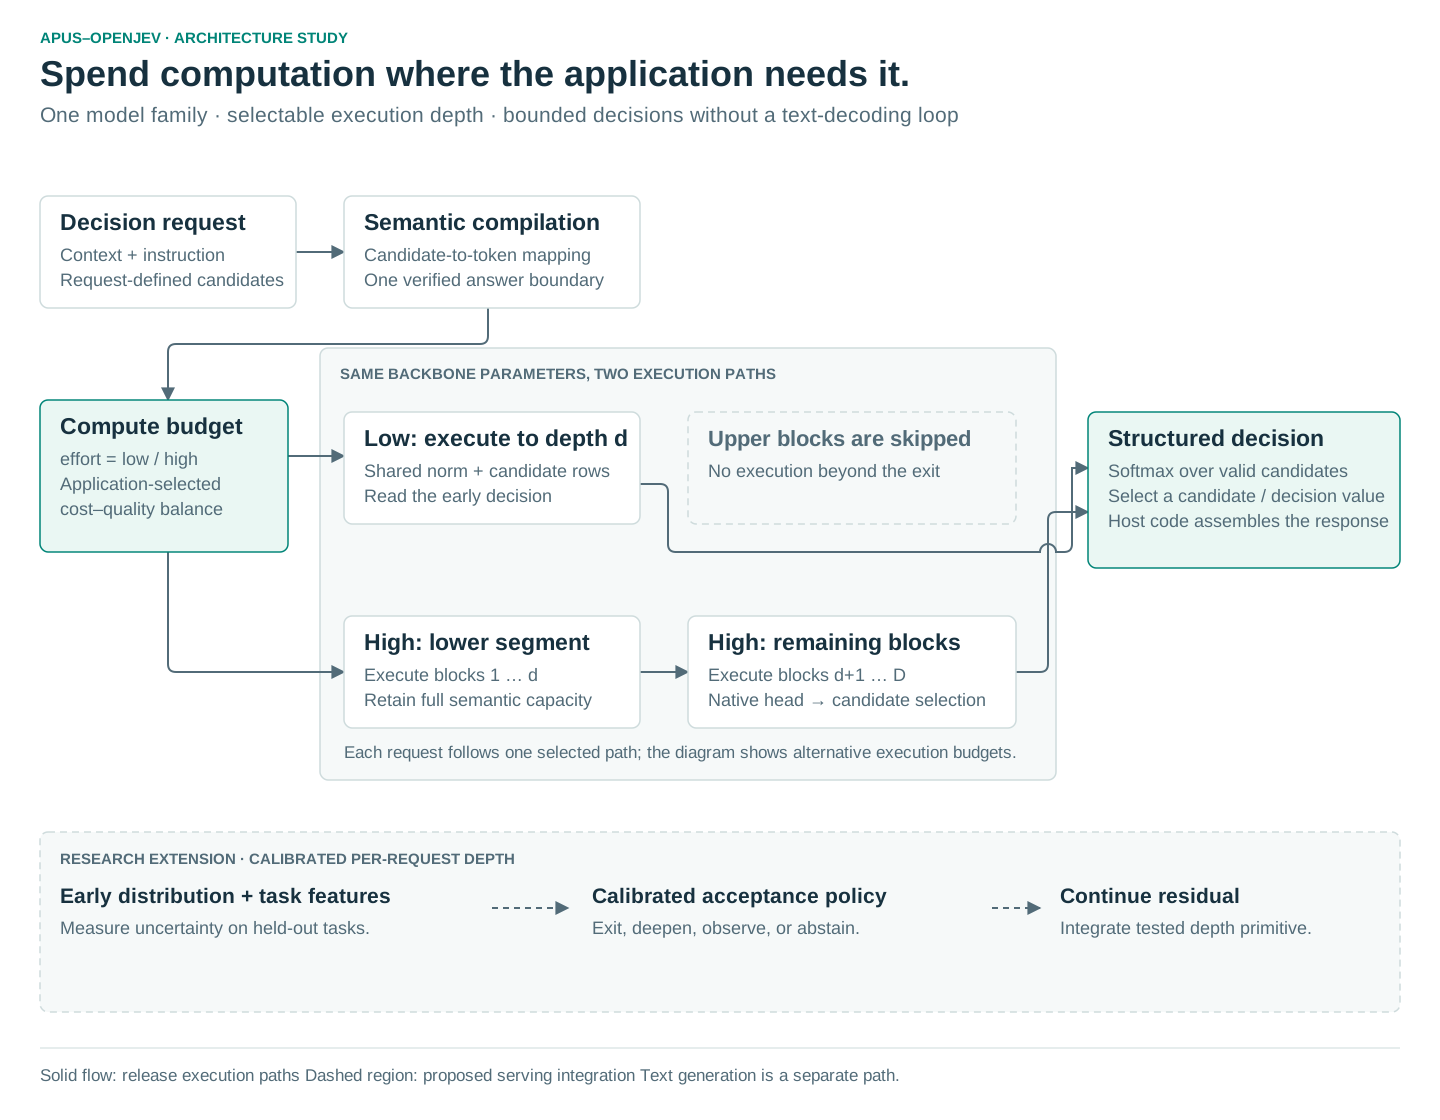
The shared prefix builds a contextual representation of the instruction, evidence, and candidate semantics. An earlier readout extracts a candidate decision from that representation. The deeper path applies additional backbone transformations before producing its decision. Both exits use the model's language output space, preserving a common interpretation of candidate labels across depths. This avoids introducing a collection of task-specific business heads as the organizing architecture.
Depth-sensitive execution also requires a careful separation between the representation used for a decision and the state used for further computation. In the depth executor, normalization for a readout does not overwrite the residual state required by subsequent blocks. This distinction makes a shallow decision and a deeper continuation conceptually compatible. The current release establishes the selectable exit mechanisms; learned per-request routing and production continuation reuse remain separate evaluation targets.
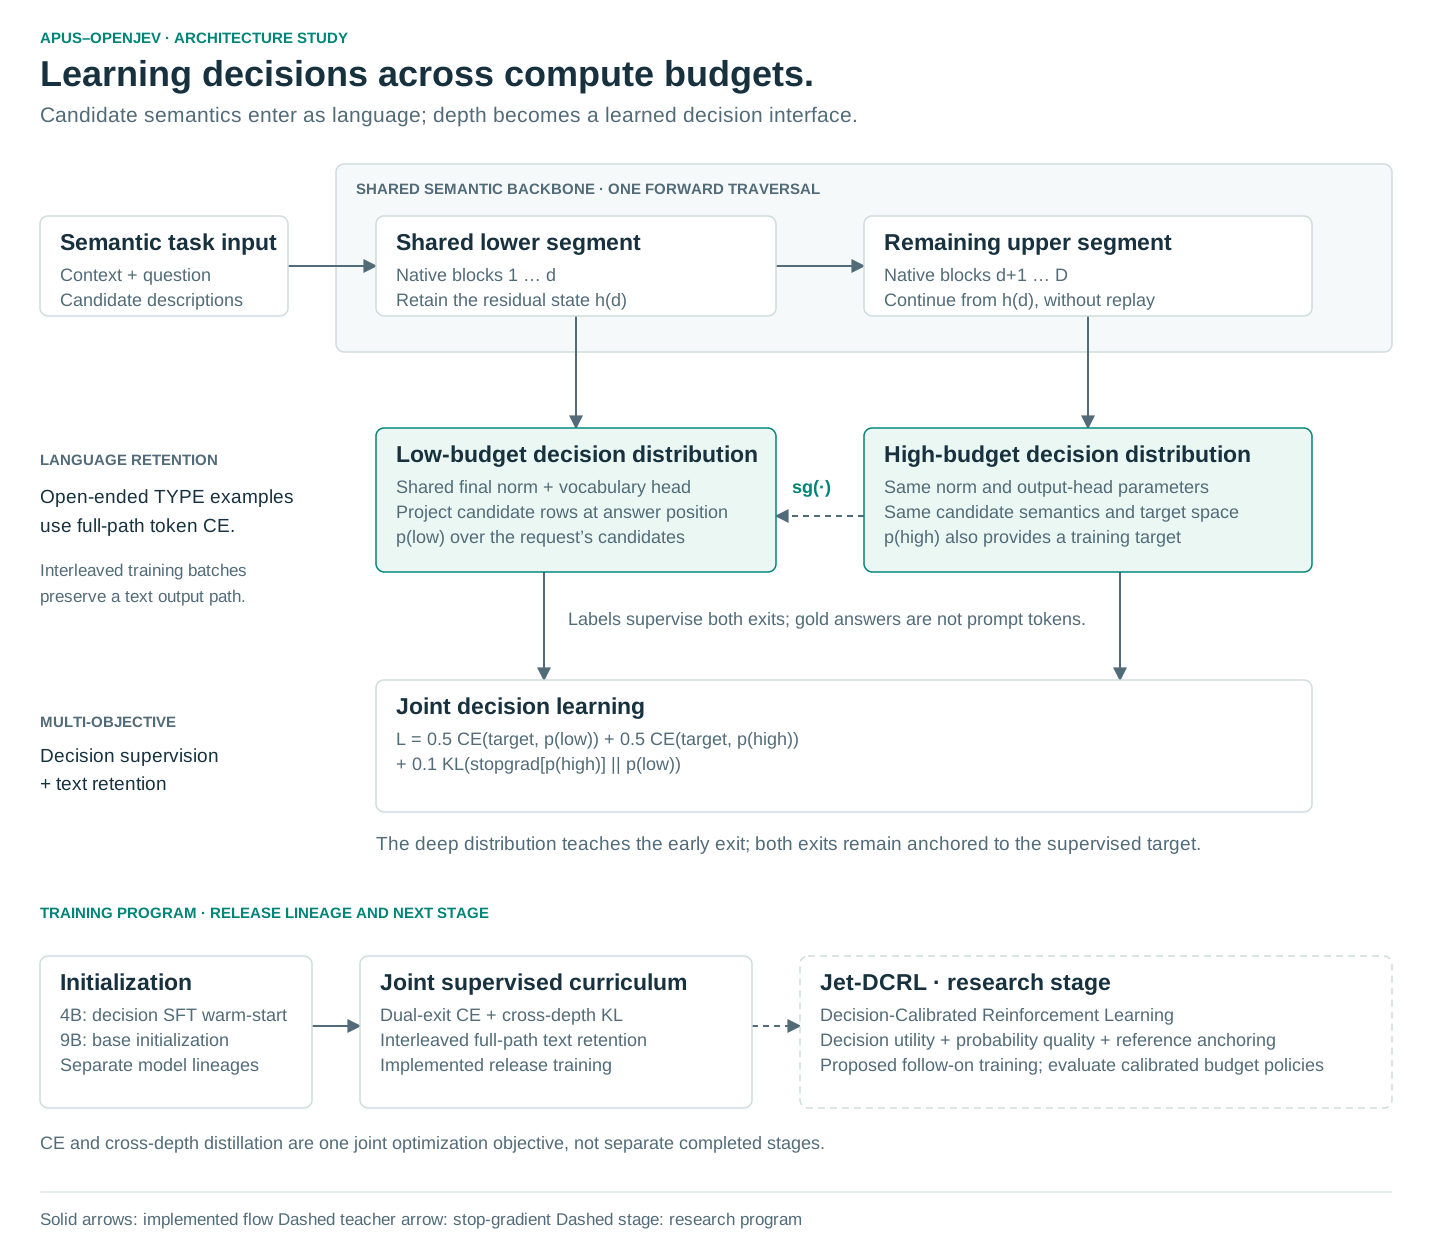
The important training question is whether an intermediate representation has acquired enough decision structure to be useful. Merely exposing an earlier layer does not answer it. Our approach therefore supervises the exits jointly and couples their candidate distributions. Lower-cost execution becomes a training objective with measurable quality, rather than an inference shortcut assumed to preserve behavior.
3. Learning Decisions and Execution Depth Together
3.1 Joint supervision and cross-depth knowledge transfer
For a supervised decision with target distribution q, the delivered objective is:

Both exits receive direct task supervision. The deeper exit additionally acts as a distributional teacher for the earlier exit. Its detached probabilities convey relative candidate preferences beyond the identity of the correct answer, while stop-gradient keeps the distillation target from being changed through that term. The deeper pathway continues to learn through its own supervised objective.
This arrangement is an internal transfer mechanism: the model learns to express useful decision structure at more than one computational budget. It is especially relevant when several candidates are plausible and the earlier exit must preserve their distinctions with fewer transformations. Its effect can be measured through the quality–cost curve of the two exits.
The supervision and transfer terms operate together during each decision update, enabling the shared model to learn both execution budgets in one coordinated optimization process.
3.2 Text co-training for workflow continuity
Some decisions lead directly to an open response: a search query, a form value, or another textual argument. TYPE examples therefore use the full-depth native text cross-entropy objective. Decision and text examples share the model while following the objective appropriate to their output space.
The resulting training interface separates bounded selection from open completion without discarding either capability. A browser-oriented system can learn which action to take and retain a path for supplying the text that action requires. This is a training design for workflow continuity; full end-to-end browser competence requires additional execution-based evaluation beyond static action selection.
3.3 A staged 4B path and an independent 9B study
The 4B model follows a concrete staged adaptation path. A full-depth starter first learns from a focused mixture of decision and TYPE examples. The resulting parameters initialize a broader run that jointly optimizes the two decision exits and the text objective. The initial stage establishes task-facing behavior; the subsequent stage introduces the shared compute-budget learning objective across a wider task mixture.
The 9B study starts independently from its own base initialization and uses the same registered curriculum and joint objective. It does not inherit the 4B starter. This provides a model-scale comparison with a common main training protocol while preserving the distinction in initialization history. The primary 9B result reported here uses an intermediate training version; the full-schedule version is also retained.
4. A Curriculum Organized Around Decision Capabilities
The main curriculum allocates 97.34% of training records to candidate decisions and 2.66% to open-text TYPE examples. The source shares below describe the registered training mixture. Related examples are tracked by parent episode, dialogue, or source context to preserve their provenance.
| Training source | Share | Capability emphasized |
|---|---|---|
| Mind2Web browser Choice | 30.22% | Selecting actions from page evidence and goals |
| Mind2Web browser TYPE | 2.66% | Producing necessary workflow text |
| HelpSteer3 principle | 21.85% | Applying a stated natural-language principle |
| Schema-Guided Dialogue | 8.62% | Decisions conditioned on dialogue and workflow state |
| GoEmotions attribute Score | 8.40% | Judging whether a specified attribute applies |
| BoolQ | 10.09% | Evidence-grounded yes/no decisions |
| MNLI | 16.81% | Entailment, contradiction, and neutral relations |
| Local counterfactual records | 1.34% | Sensitivity to decision-relevant factual changes |
Source percentages are calculated over the main training schedule and rounded to two decimal places. Their displayed sum may differ slightly from 100% because of rounding.
The common candidate interface makes these tasks compatible without erasing their differences. Browser examples ground choices in visible elements and goals; principle examples require conditioning on the rule currently provided; entailment and binary questions emphasize relations between claims and evidence. Counterfactual records target changes that should alter a decision, rather than encouraging invariance to every input perturbation.
Data conversion, candidate construction, parent grouping, and training manifests preserve the relationship between source evidence and target decisions. The main schedule is a heterogeneous task mixture; starter records and main records are tracked separately, including potential overlap.
5. Jet-DCRL: Decision Utility and Probability Quality
A useful next step is to distinguish three properties that accuracy alone cannot express: whether a decision is correct, whether its probability reflects uncertainty, and whether its consequence is valuable under the application's costs. We call this research extension Jet-DCRL — Decision-Calibrated Reinforcement Learning.
Its candidate-space objective combines proper-scoring components, reference preservation, and decision utility:

Here D denotes the set of supervised decision depths.
The NLL and Brier terms supervise probabilities at both exits. The reference term anchors the deeper distribution to a frozen reference. The utility term targets the earlier exit, where better decisions have particular value for low-cost execution. Candidate utilities are supplied as verified training information; they are not inferred merely from the model's confidence.
For bounded candidate sets, the exact utility objective is tractable:

A sampled alternative draws actions from the current shallow policy and uses an expected-utility baseline in its policy-gradient estimator. Comparing exact and sampled optimization is valuable here: when the action space is small, sampling should earn its complexity through evidence rather than being assumed necessary.
The research objective and supporting implementation are separate from the released models: the published weights in this report have not been trained with Jet-DCRL. Its purpose is to test whether utility-aware learning can improve economical decisions while preserving probability quality and deeper-path behavior. Independent NLL, Brier, reliability, and risk–coverage measurements will assess the resulting probabilities.
6. Performance: Where the Savings Can Come From
The framework offers complementary opportunities to reduce decision cost. First, a bounded decision can be obtained from candidate scores without autoregressively generating an entire structured document. Second, an earlier exit executes fewer backbone blocks. Third, selected candidate projections can reduce output-head work where the execution path supports them. These mechanisms address different components of inference and should be measured separately before their gains are combined.
The cost model includes context processing, executed depth, output projection, and any additional queries sharing the context. Shared-context execution offers a further opportunity to amortize input processing across related decisions. Its design must preserve both attention caches and the backbone's recurrent state, with numerical equivalence established before performance measurements.
Our performance target is the operating curve between useful decisions and deployment cost: end-to-end latency, sustainable request rate, memory demand, and task success under a declared workload. The serving reference now reports vLLM HTTP full-response latency on a single GPU. The standard Chat Completions path and the candidate-scoring decision service are evaluated separately because their output work differs.
6.1 Two axes of decision computation: depth and output width
Depth controls how many backbone transformations construct the decision representation. Output width controls how many language-output rows are projected from that representation. APUS Reflex's native low-effort runtime combines these axes: an earlier trained exit supplies the representation, and a candidate-aware readout restricts the output projection to the labels required by the current request. Candidate descriptions remain part of the language input; the output uses validated, unique single-token labels rather than a fixed business-category classifier.
Let hd be the normalized readout at depth d, W the language output matrix with V vocabulary rows and hidden width H, and C the request's K candidate token IDs. The two paths are:
Native low:
  input → earlier trained exit → normalized h_low
        → select W[C] and b[C] → K candidate logits → candidate softmax

Native high / current vLLM decision path:
  input → full-depth backbone → normalized h_high
        → full vocabulary projection → select candidate logits
        → candidate normalization
The candidate projection selects the output weight and bias rows before the matrix multiplication:

This avoids constructing the full vocabulary score vector before selecting its candidate entries. For the same representation, weights, bias and candidate set, these are algebraically identical. Floating-point kernels may differ numerically, so deployment equivalence still requires validation. This identity does not imply that low and high exits have the same predictions: they use different representations and executed depths.
For one decision position, the output-head arithmetic scales as:

This is an output-head cost model, not an end-to-end speedup claim. Backbone computation, memory traffic, row gathering and serving overhead remain. Candidate softmax expresses preference within the supplied set; it is not automatically calibrated confidence or the full-vocabulary probability mass.
6.2 Implemented paths and serving scope
| Runtime path | Projection order | Release behavior |
|---|---|---|
| Native low effort | Select candidate weight rows, then project | Implemented for supported linear output heads |
| Native high effort | Full vocabulary projection, then select | Retains the full-head reference path |
| vLLM decision gateway | Full vocabulary logits/logprobs, then extract and normalize candidates | Current measured HTTP path |
| Standard vLLM Chat | Standard full-vocabulary language output head | Current public launcher |
The native low executor records candidate_rows when the selected projection is used. If the output head has unsupported hooks, adapters or parametrizations, it executes the real head and selects afterward, recording full_head_fallback; this preserves the head's actual behavior. The candidate-only shortcut therefore has an explicit compatibility boundary.
Requesting only candidate log-probabilities from vLLM limits the returned results; it does not by itself reduce the output matrix multiplication. Likewise, an output-token mask can restrict choices after logits have been computed. The present vLLM measurements must not be attributed to candidate-row projection. Extending that projection to the serving engine is a separate optimization target, with matched high-depth comparisons needed to isolate its contribution from early-exit savings.
The architectural value lies in coordinating language-conditioned candidates, jointly trained execution depths and an output path sized to the decision. This preserves a shared language representation across tasks while making distinct compute costs controllable. It does not depend on treating selected matrix rows as a new attention mechanism.
7. Initial Evidence and the Evaluation Agenda
7.1 Decision accuracy
| System | Decision accuracy |
|---|---|
| APUS Reflex 4B | 82.50% |
| APUS Reflex 9B | 85.00% |
| Jev official API | 82.50% |
| Laya | 68.75% |
These results use a frozen development comparison panel of 80 questions across 79 parent groups, with 16 questions each from Browser, HelpSteer3, BoolQ, MNLI, and Score. APUS results use the high compute budget; the 85.00% 9B entry uses the selected 9B-3000 version, and Laya uses its typed, complete-input evaluation with truncation corrected. The panel has been used during development and version selection. Score evaluates a specified emotion category independently; browser questions evaluate static candidate selection. Detailed sample composition is recorded in the dataset statistics. Accuracy and serving measurements retain their respective model-version and execution-path identities.
7.2 vLLM HTTP response latency
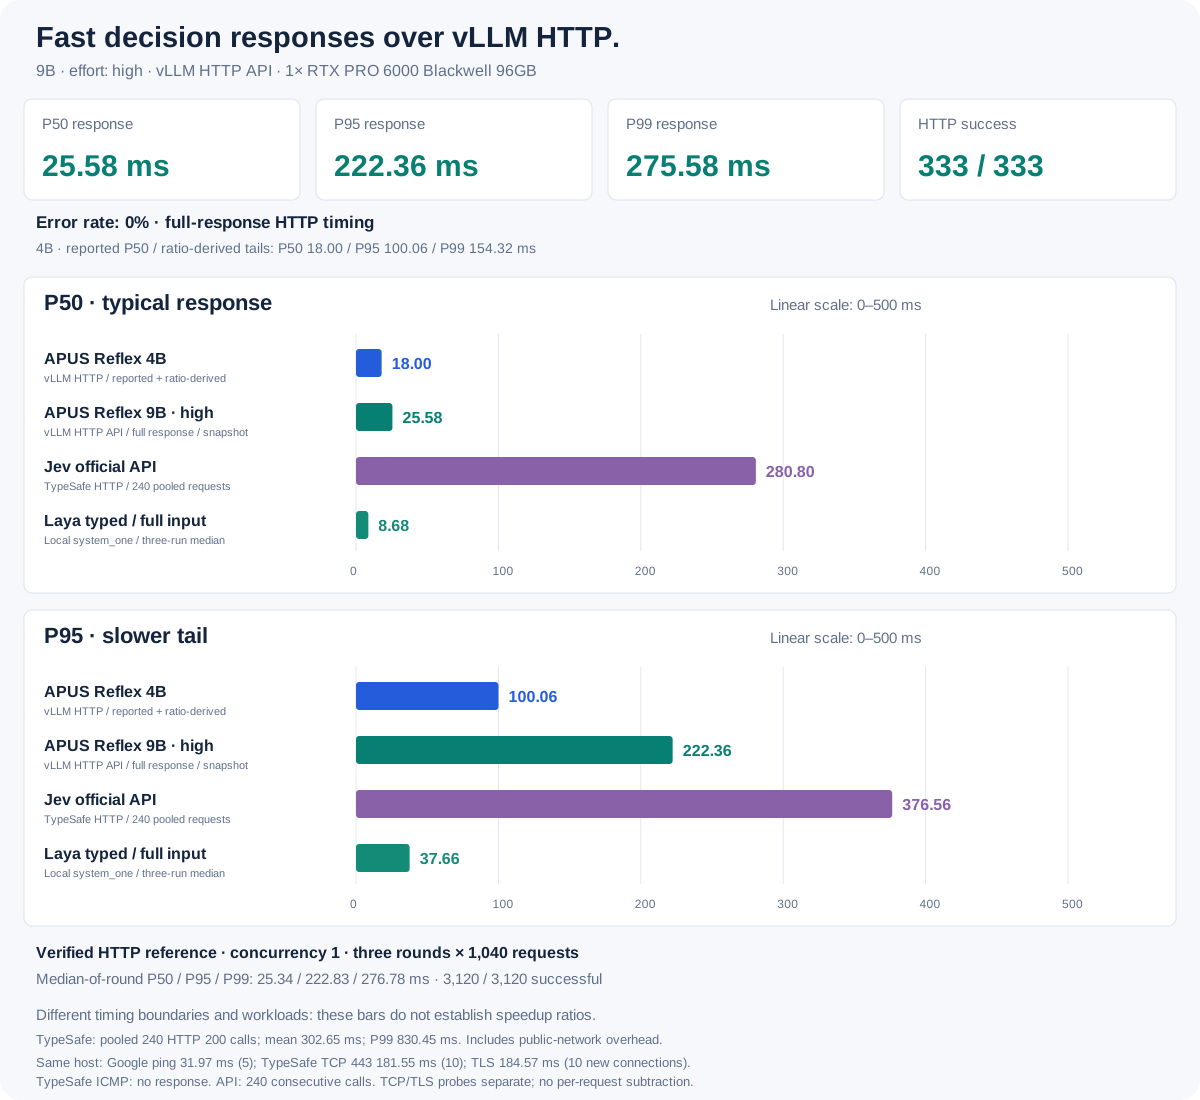
The APUS serving reference uses one RTX PRO 6000 Blackwell 96GB GPU. The 9B decision-service results below correspond to effort: high, with full HTTP response timing.
| Serving path | P50 | P95 | P99 |
|---|---|---|---|
| APUS Reflex 9B high · vLLM HTTP | 25.58 ms | 222.36 ms | 275.58 ms |
| APUS Reflex 4B · vLLM HTTP | 18.00 ms | 100.06 ms | 154.32 ms |
| Jev / TypeSafe official API · public HTTP | 280.80 ms | 376.56 ms | 830.45 ms |
| Laya typed · complete-input local pipeline | 8.68 ms | 37.66 ms | — |
The 9B-5949 high snapshot reports 333/333 successful requests and 0% errors. An independently archived three-round serial HTTP reference reports median per-round P50/P95/P99 of 25.34 / 222.83 / 276.78 ms, with 3,120/3,120 successful requests. These two run records remain separate.
The project owner supplied an updated 18 ms 4B P50 from another session. Its P95/P99 apply the reported 45% / 56% ratios to the corresponding 9B high values: 222.36 × 0.45 = 100.06 ms and 275.58 × 0.56 = 154.32 ms after rounding. These entries retain that provenance and are not presented as a new 4B request-log replay. The 9B request count is not attributed to 4B.
Jev includes public-network, queueing, and service overhead. Laya includes tokenization, transfer, inference, and output processing; its displayed percentiles are medians of three per-run statistics. Different boundaries do not establish a direct model speedup ratio. Full-response latency is distinct from streaming first-token latency and generated tokens per second. Exact display data and sources are in latency-vllm-data.json.
TypeSafe official API — updated three-round reference.
| Run | Mean HTTP response time | Accuracy |
|---|---|---|
| Round 1 | 298.83 ms | 68/80 · 85.00% |
| Round 2 | 303.55 ms | 66/80 · 82.50% |
| Round 3 | 305.57 ms | 65/80 · 81.25% |
| Overall | 302.65 ms | 199/240 · 82.92% |
The updated screenshot reports P50 280.80 ms, P95 376.56 ms and P99 830.45 ms, computed from all 240 HTTP 200 responses pooled across three rounds, rather than averaging per-round percentiles. Mean response time remains 302.65 ms. Timing includes the public-network overhead from Runpod to the official service; 80 questions repeated three times provide a sample-specific tail-latency reference. The earlier task-accuracy charts retain their original single-run results; this table records the separate three-round evaluation.
Network reference, same Runpod host: Google ICMP ping averaged 31.97 ms (about 30 ms; 5 probes). TypeSafe did not respond to ICMP ping; TCP port 443 connection averaged 181.55 ms (10 probes), and TLS handshake averaged 184.57 ms (10 new connections). The API test used 240 consecutive calls across three rounds. TCP/TLS probes were separate; their timings are not subtracted from each API request. Source: supplied measurement screenshot.
7.3 Compute effort and decision quality

The same 4B model scores 82.50% with high effort and 76.25% with low effort on the frozen panel, a difference of 6.25 percentage points, or 7.58% relative. Both execution paths have learned task supervision. Applications select the native runtime's budget based on their quality and computation requirements.
The standard vLLM launcher serves the full-depth model. Selectable native exits do not by themselves establish a low-effort vLLM HTTP implementation. Reported serving timings should therefore stay attached to the actual evaluated execution path. See effort-tradeoff-data.json for the paired quality record.
7.4 Public deployment verification
The released deployment/serve_vllm.py was downloaded anonymously from apus-ailab/APUS-Reflex, together with the 9B-5949 merged weights into a fresh cache. A single RTX PRO 6000 Blackwell 96GB GPU served the model through vLLM 0.29.0 and the OpenAI-compatible Chat Completions endpoint. The tested environment used Python 3.12.3, PyTorch 2.13.0, Transformers 5.17.0 and a CUDA 13 compiler. The installed Python environment was reused; this was not a clean operating-system installation test.
The fixed panel was replayed three times: 240/240 requests succeeded, all returned valid candidate labels, and no completion was truncated. Each round reproduced 67/80 correct for the 9B-5949 serving version. Full local HTTP P50/P95/P99 were 45.47 / 191.36 / 232.29 ms. These Chat Completions results are distinct from the candidate-scoring decision HTTP reference in Section 7.2 and from the selected 9B-3000 accuracy result in Section 7.1.
The literal initial README example exposed a reproducibility issue: a 16-token limit with thinking enabled truncated before producing the decision. Setting chat_template_kwargs.enable_thinking=False resolved it. The corrected OpenAI SDK example returned A with finish_reason="stop". The model README contains the tested installation, startup and request settings.
7.5 Evaluation agenda
The next evaluation phase should connect each architectural claim to an appropriate experiment. Depth learning requires matched initialization and data controls against full-depth-only training. Routing requires frozen policies, per-task risk–coverage curves, and a measured relationship between saved computation and errors. Shared-state execution requires numerical and decision-equivalence checks before latency tests. Browser capability requires replayable environments, action and TYPE evaluation, recovery behavior, and complete task outcomes. Jet-DCRL requires comparisons against continued supervision and exact utility optimization, with probability metrics reported alongside accuracy.
APUS Reflex establishes a concrete foundation for this program: language-conditioned decisions, shared parameters across execution budgets, and a training objective that connects those budgets. Its central direction is to make computational effort a controllable dimension of useful language-model behavior, evaluated through decisions and the workflows they enable.
Acknowledgments
We thank the Qwen team for the Qwen3.5-4B and Qwen3.5-9B base models, the ms-swift contributors for the training framework, and the creators of the open datasets used in this work.