Text Generation
GGUF
llama.cpp
quantized
conversational
imatrix
archsloth
autoround
kl-divergence
multilingual
korean
code
local-llm
cpu
on-device
qwen3
4b
Instructions to use Archsloth/Qwen3-4B-GGUF with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- llama.cpp
How to use Archsloth/Qwen3-4B-GGUF with llama.cpp:
Install (macOS, Linux)
curl -LsSf https://llama.app/install.sh | sh # Start a local OpenAI-compatible server with a web UI: llama serve -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M # Run inference directly in the terminal: llama cli -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M
Install from WinGet (Windows)
winget install llama.cpp # Start a local OpenAI-compatible server with a web UI: llama serve -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M # Run inference directly in the terminal: llama cli -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M
Use pre-built binary
# Download pre-built binary from: # https://github.com/ggerganov/llama.cpp/releases # Start a local OpenAI-compatible server with a web UI: ./llama-server -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M # Run inference directly in the terminal: ./llama-cli -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M
Build from source code
git clone https://github.com/ggerganov/llama.cpp.git cd llama.cpp cmake -B build cmake --build build -j --target llama-server llama-cli # Start a local OpenAI-compatible server with a web UI: ./build/bin/llama-server -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M # Run inference directly in the terminal: ./build/bin/llama-cli -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M
Use Docker
docker model run hf.co/Archsloth/Qwen3-4B-GGUF:Q4_K_M
- LM Studio
- Jan
- vLLM
How to use Archsloth/Qwen3-4B-GGUF with vLLM:
Install from pip and serve model
# Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "Archsloth/Qwen3-4B-GGUF" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "Archsloth/Qwen3-4B-GGUF", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }'Use Docker
docker model run hf.co/Archsloth/Qwen3-4B-GGUF:Q4_K_M
- Ollama
How to use Archsloth/Qwen3-4B-GGUF with Ollama:
ollama run hf.co/Archsloth/Qwen3-4B-GGUF:Q4_K_M
- Unsloth Desktop
- Pi
How to use Archsloth/Qwen3-4B-GGUF with Pi:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M
Configure the model in Pi
# Install Pi: npm install -g @earendil-works/pi-coding-agent # Add to ~/.pi/agent/models.json: { "providers": { "llama-cpp": { "baseUrl": "http://localhost:8080/v1", "api": "openai-completions", "apiKey": "none", "models": [ { "id": "Archsloth/Qwen3-4B-GGUF:Q4_K_M" } ] } } }Run Pi
# Start Pi in your project directory: pi
- Docker Model Runner
How to use Archsloth/Qwen3-4B-GGUF with Docker Model Runner:
docker model run hf.co/Archsloth/Qwen3-4B-GGUF:Q4_K_M
- Lemonade
How to use Archsloth/Qwen3-4B-GGUF with Lemonade:
Pull the model
# Download Lemonade from https://lemonade-server.ai/ lemonade pull Archsloth/Qwen3-4B-GGUF:Q4_K_M
Run and chat with the model
lemonade run user.Qwen3-4B-GGUF-Q4_K_M
List all available models
lemonade list
- Hermes Agent
How to use Archsloth/Qwen3-4B-GGUF with Hermes Agent:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M
Configure Hermes
# Install Hermes: curl -fsSL https://hermes-agent.nousresearch.com/install.sh | bash hermes setup # Point Hermes at the local server: hermes config set model.provider custom hermes config set model.base_url http://127.0.0.1:8080/v1 hermes config set model.default Archsloth/Qwen3-4B-GGUF:Q4_K_M
Run Hermes
hermes
- Atomic Chat
- OpenClaw
How to use Archsloth/Qwen3-4B-GGUF with OpenClaw:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf Archsloth/Qwen3-4B-GGUF:Q4_K_M
Configure OpenClaw
# Install OpenClaw: npm install -g openclaw@latest # Register the local server and set it as the default model: openclaw onboard --non-interactive --mode local \ --auth-choice custom-api-key \ --custom-base-url http://127.0.0.1:8080/v1 \ --custom-model-id "Archsloth/Qwen3-4B-GGUF:Q4_K_M" \ --custom-provider-id llama-cpp \ --custom-compatibility openai \ --custom-text-input \ --accept-risk \ --skip-health
Run OpenClaw
openclaw agent --local --agent main --message "Hello from Hugging Face"
|
Download article_models.svg from Archsloth/Qwen3-4B-GGUF: direct link, hf CLI and curl.
- Browser
- Download file 4.87 kB
-
https://huggingface.co/Archsloth/Qwen3-4B-GGUF/resolve/main/article_models.svg
- Command line
-
hf download hf://Archsloth/Qwen3-4B-GGUF/article_models.svg
-
curl -L -o article_models.svg https://huggingface.co/Archsloth/Qwen3-4B-GGUF/resolve/main/article_models.svg
4.87 kB
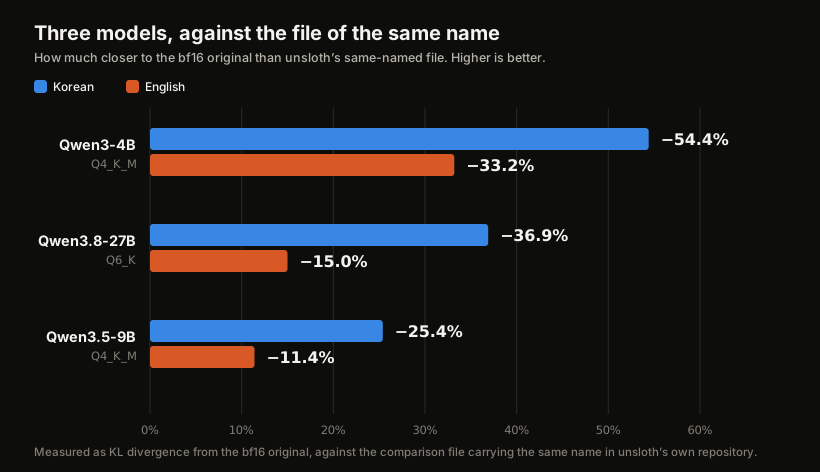
| <svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 820 472" width="820" height="472" font-family="ui-sans-serif,-apple-system,'Segoe UI',Roboto,'Helvetica Neue',Arial,sans-serif" role="img" aria-label="Three models, against the file of the same name"> | |
| <rect width="820" height="472" fill="#0d0d0c"/> | |
| <text x="34" y="40" fill="#f4f3ee" font-size="20" font-weight="700">Three models, against the file of the same name</text> | |
| <text x="34" y="62" fill="#b6b4a8" font-size="12.5">How much closer to the bf16 original than unsloth’s same-named file. Higher is better.</text> | |
| <rect x="34" y="80" width="13" height="13" rx="3" fill="#3987e5"/> | |
| <text x="53" y="91" fill="#f4f3ee" font-size="12">Korean</text> | |
| <rect x="126" y="80" width="13" height="13" rx="3" fill="#d95926"/> | |
| <text x="145" y="91" fill="#f4f3ee" font-size="12">English</text> | |
| <line x1="150.0" y1="108" x2="150.0" y2="414" stroke="#2a2a26" stroke-width="1"/> | |
| <text x="150.0" y="434" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="middle">0%</text> | |
| <line x1="241.7" y1="108" x2="241.7" y2="414" stroke="#2a2a26" stroke-width="1"/> | |
| <text x="241.7" y="434" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="middle">10%</text> | |
| <line x1="333.3" y1="108" x2="333.3" y2="414" stroke="#2a2a26" stroke-width="1"/> | |
| <text x="333.3" y="434" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="middle">20%</text> | |
| <line x1="425.0" y1="108" x2="425.0" y2="414" stroke="#2a2a26" stroke-width="1"/> | |
| <text x="425.0" y="434" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="middle">30%</text> | |
| <line x1="516.7" y1="108" x2="516.7" y2="414" stroke="#2a2a26" stroke-width="1"/> | |
| <text x="516.7" y="434" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="middle">40%</text> | |
| <line x1="608.3" y1="108" x2="608.3" y2="414" stroke="#2a2a26" stroke-width="1"/> | |
| <text x="608.3" y="434" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="middle">50%</text> | |
| <line x1="700.0" y1="108" x2="700.0" y2="414" stroke="#2a2a26" stroke-width="1"/> | |
| <text x="700.0" y="434" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="middle">60%</text> | |
| <text x="136" y="150" fill="#f4f3ee" font-size="14.5" font-weight="600" text-anchor="end">Qwen3-4B</text> | |
| <text x="136" y="168" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="end">Q4_K_M</text> | |
| <rect x="150" y="128" width="498.7" height="22" rx="3" fill="#3987e5"/> | |
| <text x="660.7" y="145" fill="#f4f3ee" font-size="16" font-weight="700" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace">−54.4%</text> | |
| <rect x="150" y="154" width="304.3" height="22" rx="3" fill="#d95926"/> | |
| <text x="466.3" y="171" fill="#f4f3ee" font-size="16" font-weight="700" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace">−33.2%</text> | |
| <text x="136" y="246" fill="#f4f3ee" font-size="14.5" font-weight="600" text-anchor="end">Qwen3.8-27B</text> | |
| <text x="136" y="264" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="end">Q6_K</text> | |
| <rect x="150" y="224" width="338.2" height="22" rx="3" fill="#3987e5"/> | |
| <text x="500.2" y="241" fill="#f4f3ee" font-size="16" font-weight="700" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace">−36.9%</text> | |
| <rect x="150" y="250" width="137.5" height="22" rx="3" fill="#d95926"/> | |
| <text x="299.5" y="267" fill="#f4f3ee" font-size="16" font-weight="700" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace">−15.0%</text> | |
| <text x="136" y="342" fill="#f4f3ee" font-size="14.5" font-weight="600" text-anchor="end">Qwen3.5-9B</text> | |
| <text x="136" y="360" fill="#807d72" font-size="11.5" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace" text-anchor="end">Q4_K_M</text> | |
| <rect x="150" y="320" width="232.8" height="22" rx="3" fill="#3987e5"/> | |
| <text x="394.8" y="337" fill="#f4f3ee" font-size="16" font-weight="700" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace">−25.4%</text> | |
| <rect x="150" y="346" width="104.5" height="22" rx="3" fill="#d95926"/> | |
| <text x="266.5" y="363" fill="#f4f3ee" font-size="16" font-weight="700" font-family="ui-monospace,SFMono-Regular,Menlo,Consolas,monospace">−11.4%</text> | |
| <text x="34" y="456" fill="#807d72" font-size="11.5">Measured as KL divergence from the bf16 original, against the comparison file carrying the same name in unsloth’s own repository.</text> | |
| </svg> |