

Statim Decide Multilingual Base
Licence. This version was trained partly on data that is non-commercial, ShareAlike or under an unknown licence (the same training mixture as 0.7.0; findings in DATA_LICENSES.md). The weights are offered only under PolyForm Noncommercial 1.0.0. A version trained only on cleared data will follow.
A decision model for Statim, the native C++ engine for typed decisions: ask any text a
choice, a score or a yes/no question and get calibrated answers from one forward pass, on
CPU or GPU, without Python at runtime. Version 0.10.0, fine-tuned from
convaiinnovations/laya-multilingual (mmBERT-base encoder).
▶ Try it live in your browser: this model on a free CPU, no install and no key.

One support ticket, three typed answers, one forward pass: the 60-second film.
On a public benchmark: S1Bench
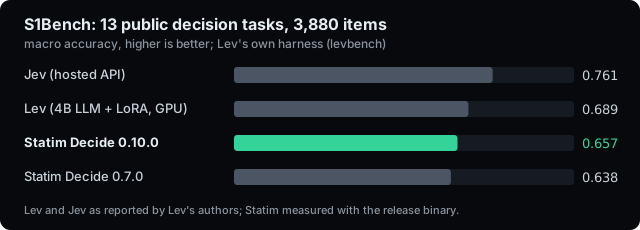
S1Bench is a public suite of 13 typed-decision tasks (3,880 items), run here with levbench, the harness the authors of Lev used. This version scores 0.657 macro accuracy, up from 0.638 for 0.7.0. It is still behind Lev, a 4B LLM with LoRA on a GPU (0.689), and the hosted Jev (0.761). Mean calibration error (ECE): 0.126, against 0.138 for 0.7.0. No single subset changed significantly against 0.7.0 (paired exact McNemar, Holm); the gain is spread over many subsets. The same file gave the same answer to every item on each device; median server time per request: 167 ms on CPU (Ryzen 7 5800X, 4 threads), 22 ms on GPU (RTX 3070, Vulkan) (p95 568 ms, 50 ms).
| Macro accuracy | This model | 0.7.0 | Lev | Jev |
|---|---|---|---|---|
| all 13 subsets | 0.657 | 0.638 | 0.689 | 0.761 |
| 7 subsets from sources Statim never trained on | 0.584 | 0.565 | 0.635 | 0.766 |
| 6 subsets of the public board snapshot | 0.675 | 0.648 | 0.719 | 0.769 |
6 subsets are in-domain for Statim (it trained on their sources' train splits; S1Bench uses their test or dev splits), so the never-trained row is the fair comparison. Lev and Jev numbers are quoted from Lev's own report, not re-measured. Protocol, per-subset results and paired tests: s1bench-0.10.0-2026-10-07.md.
Quick start
# Statim release binary: https://github.com/BEKO2210/statim/releases
huggingface-cli download Beko2210/statim-decide-multilingual-base statim-decide-multilingual-base-q8_0.gguf --local-dir models
./statim serve -m multilingual=models/statim-decide-multilingual-base-q8_0.gguf --port 8080
curl -s localhost:8080/v1/systemone -d '{
  "state": {"subject": "Duplicate charge on invoice #4411",
            "body": "We were billed twice for March. Please refund the second charge."},
  "questions": {
    "department": {"type": "choice", "instructions": "Which department should handle this?",
      "criteria": {"billing": "invoices, refunds", "technical": "bugs, outages", "sales": "pricing, contracts"}},
    "urgency": {"type": "score", "instructions": "How urgent is this request?",
      "criteria": ["not urgent", "soon", "critical"]},
    "refund": {"type": "noul", "instructions": "Does the user explicitly request a refund?"}}}'
Open http://127.0.0.1:8080/ for the playground. API reference: docs/API.md.
Files
| File | Size | Use |
|---|---|---|
statim-decide-multilingual-base-f32.gguf |
0.91 GB | reference precision, exact on GPU |
statim-decide-multilingual-base-q8_0.gguf |
0.36 GB | smaller; slower than f32 on AVX2 CPUs, faster on ARM dotprod and CUDA |
checkpoint/ |
0.68 GB | Laya-format checkpoint for fine-tuning and the Python reference |
Checksums in SHA256SUMS. The f32 file reproduces the reference implementation within 1e-4 on
Statim's parity tests. q8_0 is 2.5x smaller with slightly different logits. Whether it
is faster depends on the hardware: on x86-64 CPUs with AVX2 but without int8 dot-product
instructions it is slower than f32; on ARM CPUs with dot-product instructions and with CUDA it is
faster (measurements).
Evaluation
Measured by Statim's no-harm gate (tools/finetune/gate.py)
on held-out test data the model selection never looked at. Against the previous release 0.7.0 (same held-out item pool), on 91 held-out suites: 6 significant gains, 85 within noise, 0 regressions (paired exact McNemar tests; gains and regressions are separately significant after Holm-Bonferroni over all suites).
| Suite | Role | This model | 0.7.0 | Protocol |
|---|---|---|---|---|
| typed-decisions | trained | 0.7750 | 0.7630 | test split, first 2,000 decisions; its train split is replay data |
| Banking77 | trained | 0.9185 | 0.9140 | test split, first 2,000 rows, all 77 intents in one question |
| MASSIVE intents | trained | 0.8161 | 0.7995 | mean over 12 languages, 150 seeded stratified test rows each |
| AG News | held out | 0.9210 | 0.9295 | zero-shot (never trained on), first 2,000 test rows |
| DAIR Emotion | held out | 0.5305 | 0.5040 | zero-shot, first 2,000 test rows |
| HWU64 intents | held out | 0.8533 | 0.7867 | English, 150 rows; rows overlapping MASSIVE removed |
| SIB-200 topics | held out | 0.7967 | 0.7817 | zero-shot, mean over 4 languages, 150 rows each |
| Sentiment | held out | 0.6311 | 0.6050 | zero-shot, mean over 12 languages, 150 rows each |
| HateCheck | held out | 0.6461 | 0.6358 | zero-shot, mean over 11 languages, 150 rows each |
| Belebele reading | held out | 0.2800 | 0.2583 | zero-shot, mean over 4 languages, 150 rows each |
Decision categories
One held-out suite per decision category, built from splits of the training sources that the mixture never loads; any text that also occurs in the training mixture is dropped. 150 items per language, macro over languages.
| Category | Languages | This model | 0.7.0 |
|---|---|---|---|
| complaint | en | 0.820 | 0.767 |
| emotion | de, en, es, fr, hi, pt, ru, zh | 0.661 | 0.589 |
| fact check | en | 0.467 | 0.313 |
| formality | ja, tr | 0.953 | 0.773 |
| intent | en, nl, tr | 0.793 | 0.753 |
| nli | en, ja, tr | 0.769 | 0.747 |
| pii | ar, de, en, es, fr, it, ja, nl, ru, sv, zh | 0.909 | 0.856 |
| reading | en | 0.933 | 0.927 |
| safety | en | 0.880 | 0.727 |
| sentiment | en, zh | 0.877 | 0.800 |
| similarity | pt | 0.880 | 0.833 |
| stance | en | 0.980 | 0.893 |
| topic | en | 0.647 | 0.607 |
| urgency | en | 0.987 | 0.893 |
Published systems under the same protocol, for orientation: typed-decisions meraGPT 0.768, laya-typed-decisions 0.766, Jev 0.727; AG News zero-shot Laya 0.950, GPT-3 (CARP) 0.926, Jev 0.881; Banking77 supervised MPNet 0.941; MASSIVE XLM-R base 0.857 over 12 languages (full train set). Sources: docs/ROADMAP.md.
All 91 held-out suites
| Suite | Accuracy | Rows |
|---|---|---|
amazon_massive_intent/ar |
0.7400 | 150 |
amazon_massive_intent/de |
0.8267 | 150 |
amazon_massive_intent/en |
0.8467 | 150 |
amazon_massive_intent/es |
0.8333 | 150 |
amazon_massive_intent/fr |
0.8067 | 150 |
amazon_massive_intent/hi |
0.7800 | 150 |
amazon_massive_intent/it |
0.8133 | 150 |
amazon_massive_intent/ja |
0.8333 | 150 |
amazon_massive_intent/pl |
0.8333 | 150 |
amazon_massive_intent/ru |
0.8467 | 150 |
amazon_massive_intent/tr |
0.8133 | 150 |
amazon_massive_intent/zh-CN |
0.8200 | 150 |
belebele/ar |
0.2600 | 150 |
belebele/de |
0.3200 | 150 |
belebele/en |
0.3133 | 150 |
belebele/hi |
0.2267 | 150 |
categories:complaint/en |
0.8200 | 150 |
categories:emotion/de |
0.4867 | 150 |
categories:emotion/en |
0.6400 | 150 |
categories:emotion/es |
0.6200 | 150 |
categories:emotion/fr |
0.8267 | 150 |
categories:emotion/hi |
0.8600 | 150 |
categories:emotion/pt |
0.5600 | 150 |
categories:emotion/ru |
0.7400 | 150 |
categories:emotion/zh |
0.5533 | 150 |
categories:fact_check/en |
0.4667 | 150 |
categories:formality/ja |
0.9067 | 150 |
categories:formality/tr |
1.0000 | 150 |
categories:intent/en |
0.8467 | 150 |
categories:intent/nl |
0.5333 | 150 |
categories:intent/tr |
1.0000 | 150 |
categories:nli/en |
0.8000 | 150 |
categories:nli/ja |
0.6600 | 150 |
categories:nli/tr |
0.8467 | 150 |
categories:pii/ar |
0.9333 | 150 |
categories:pii/de |
0.8867 | 150 |
categories:pii/en |
0.9333 | 150 |
categories:pii/es |
0.8867 | 150 |
categories:pii/fr |
0.9133 | 150 |
categories:pii/it |
0.9000 | 150 |
categories:pii/ja |
0.9267 | 150 |
categories:pii/nl |
0.8533 | 150 |
categories:pii/ru |
0.9667 | 150 |
categories:pii/sv |
0.8733 | 150 |
categories:pii/zh |
0.9267 | 150 |
categories:reading/en |
0.9333 | 150 |
categories:safety/en |
0.8800 | 150 |
categories:sentiment/en |
0.8533 | 150 |
categories:sentiment/zh |
0.9000 | 150 |
categories:similarity/pt |
0.8800 | 150 |
categories:stance/en |
0.9800 | 150 |
categories:topic/en |
0.6467 | 150 |
categories:urgency/en |
0.9867 | 150 |
farstail/fa |
0.6533 | 150 |
go_emotions/en |
0.4533 | 150 |
hwu64/en |
0.8533 | 150 |
indonli/id |
0.7000 | 150 |
multi_hatecheck/ar |
0.6667 | 150 |
multi_hatecheck/de |
0.6733 | 150 |
multi_hatecheck/en |
0.6467 | 150 |
multi_hatecheck/es |
0.6467 | 150 |
multi_hatecheck/fr |
0.6600 | 150 |
multi_hatecheck/hi |
0.5800 | 150 |
multi_hatecheck/it |
0.6200 | 150 |
multi_hatecheck/nl |
0.6467 | 150 |
multi_hatecheck/pl |
0.6533 | 150 |
multi_hatecheck/pt |
0.6733 | 150 |
multi_hatecheck/zh |
0.6400 | 150 |
multilingual_sentiments/ar |
0.6333 | 150 |
multilingual_sentiments/de |
0.5600 | 150 |
multilingual_sentiments/en |
0.7200 | 150 |
multilingual_sentiments/es |
0.6000 | 150 |
multilingual_sentiments/fr |
0.6267 | 150 |
multilingual_sentiments/hi |
0.5400 | 150 |
multilingual_sentiments/id |
0.7800 | 150 |
multilingual_sentiments/it |
0.6467 | 150 |
multilingual_sentiments/ja |
0.6800 | 150 |
multilingual_sentiments/ms |
0.5333 | 150 |
multilingual_sentiments/pt |
0.6400 | 150 |
multilingual_sentiments/zh |
0.6133 | 150 |
semrel/ar |
0.2733 | 150 |
semrel/en |
0.2800 | 150 |
semrel/hi |
0.2933 | 150 |
sib200/ar |
0.7800 | 150 |
sib200/de |
0.8267 | 150 |
sib200/en |
0.8467 | 150 |
sib200/hi |
0.7333 | 150 |
test/ag_news |
0.9210 | 2000 |
test/banking77 |
0.9185 | 2000 |
test/emotion |
0.5305 | 2000 |
test/typed_decisions |
0.7750 | 2000 |
Reproduce these numbers: REPRODUCE.md.
Training
A uniform weight average (model soup, Wortsman et al., 2022) of 3 runs of train_multitask.py --clean from checkpoint laya-multilingual-big1 (0.4.0), which differ only in seed and batch order (best epochs 12/raw, 10/raw, 7/ema, each selected on validation data only); the temperatures were refitted on the validation items afterwards (--calibrate-only). Training data: the 0.7.0 mixture (Banking77, MASSIVE, typed-decisions replay, a tasksource mixture, Nemotron-Safety-Guard, IndicGuard, MINDS-14, SNIPS and further sources), including the sources the 2026-10-03 licence audit found non-commercial, ShareAlike or unlicensed; every source and finding is listed in DATA_LICENSES.md. Evaluation test rows were removed from the training data.
Intended use and limits
- Classification-style decisions over short texts and JSON: routing, triage, moderation, intent, yes/no checks, ordinal ratings. It does not generate text.
- Accuracy varies by task and language (see the table). Reading comprehension (Belebele) and semantic similarity are weak; do not use it for them without your own evaluation.
- Use the confidence: Statim's
min_confidenceoption marks low-confidence answers withescalate: trueso a person can review them. Do not automate high-stakes decisions about people without human review.
Licence
The weights may be used only under PolyForm Noncommercial 1.0.0 (text in LICENSE-MODEL.md); the Small Business, Free Trial and commercial licences do not apply to this version. The Statim engine is Apache-2.0.
Built on Laya (Apache-2.0) and mmBERT-base (MIT). Training data attribution: Banking77 (Casanueva et al., 2020, PolyAI), MASSIVE (FitzGerald et al., 2022, Amazon), and the CC-BY sources in DATA_LICENSES.md. Statim is independent and not affiliated with the Laya authors.
- Downloads last month
- 262
8-bit
32-bit
Model tree for Beko2210/statim-decide-multilingual-base
Datasets used to train Beko2210/statim-decide-multilingual-base
Space using Beko2210/statim-decide-multilingual-base 1
Evaluation results
- accuracy on typed-decisions (test split, first 2,000 decisions; its train split is replay data)self-reported0.775
- accuracy on Banking77 (test split, first 2,000 rows, all 77 intents in one question)self-reported0.918
- accuracy on MASSIVE intents (mean over 12 languages, 150 seeded stratified test rows each)self-reported0.816
- accuracy on AG News (zero-shot (never trained on), first 2,000 test rows)self-reported0.921
- accuracy on DAIR Emotion (zero-shot, first 2,000 test rows)self-reported0.530
- accuracy on HWU64 intents (English, 150 rows; rows overlapping MASSIVE removed)self-reported0.853
- accuracy on SIB-200 topics (zero-shot, mean over 4 languages, 150 rows each)self-reported0.797
- accuracy on Sentiment (zero-shot, mean over 12 languages, 150 rows each)self-reported0.631