Instructions to use NousResearch/Yarn-Mistral-7b-128k with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Libraries
- Transformers
How to use NousResearch/Yarn-Mistral-7b-128k with Transformers:
# Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("text-generation", model="NousResearch/Yarn-Mistral-7b-128k", trust_remote_code=True)# pip install -U transformers accelerate # Load model directly from transformers import AutoTokenizer, AutoModelForCausalLM tokenizer = AutoTokenizer.from_pretrained("NousResearch/Yarn-Mistral-7b-128k", trust_remote_code=True) model = AutoModelForCausalLM.from_pretrained("NousResearch/Yarn-Mistral-7b-128k", trust_remote_code=True, device_map="auto") - Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- vLLM
How to use NousResearch/Yarn-Mistral-7b-128k with vLLM:
Install from pip and serve model
# Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "NousResearch/Yarn-Mistral-7b-128k" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "NousResearch/Yarn-Mistral-7b-128k", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'Use Docker
docker model run hf.co/NousResearch/Yarn-Mistral-7b-128k
- SGLang
How to use NousResearch/Yarn-Mistral-7b-128k with SGLang:
Install from pip and serve model
# Install SGLang from pip: pip install sglang # Start the SGLang server: python3 -m sglang.launch_server \ --model-path "NousResearch/Yarn-Mistral-7b-128k" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "NousResearch/Yarn-Mistral-7b-128k", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'Use Docker images
docker run --gpus all \ --shm-size 32g \ -p 30000:30000 \ -v ~/.cache/huggingface:/root/.cache/huggingface \ --env "HF_TOKEN=<secret>" \ --ipc=host \ lmsysorg/sglang:latest \ python3 -m sglang.launch_server \ --model-path "NousResearch/Yarn-Mistral-7b-128k" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "NousResearch/Yarn-Mistral-7b-128k", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }' - Docker Model Runner
How to use NousResearch/Yarn-Mistral-7b-128k with Docker Model Runner:
docker model run hf.co/NousResearch/Yarn-Mistral-7b-128k
|
Download README.md from NousResearch/Yarn-Mistral-7b-128k: direct link, hf CLI and curl.
- Browser
- Download file 2.78 kB
-
https://huggingface.co/NousResearch/Yarn-Mistral-7b-128k/resolve/main/README.md
- Command line
-
hf download hf://NousResearch/Yarn-Mistral-7b-128k/README.md
-
curl -L -o README.md https://huggingface.co/NousResearch/Yarn-Mistral-7b-128k/resolve/main/README.md
2.78 kB
| datasets: | |
| - emozilla/yarn-train-tokenized-16k-mistral | |
| metrics: | |
| - perplexity | |
| library_name: transformers | |
| license: apache-2.0 | |
| language: | |
| - en | |
| # Model Card: Nous-Yarn-Mistral-7b-128k | |
| [Preprint (arXiv)](https://arxiv.org/abs/2309.00071) | |
| [GitHub](https://github.com/jquesnelle/yarn) | |
|  | |
| ## Model Description | |
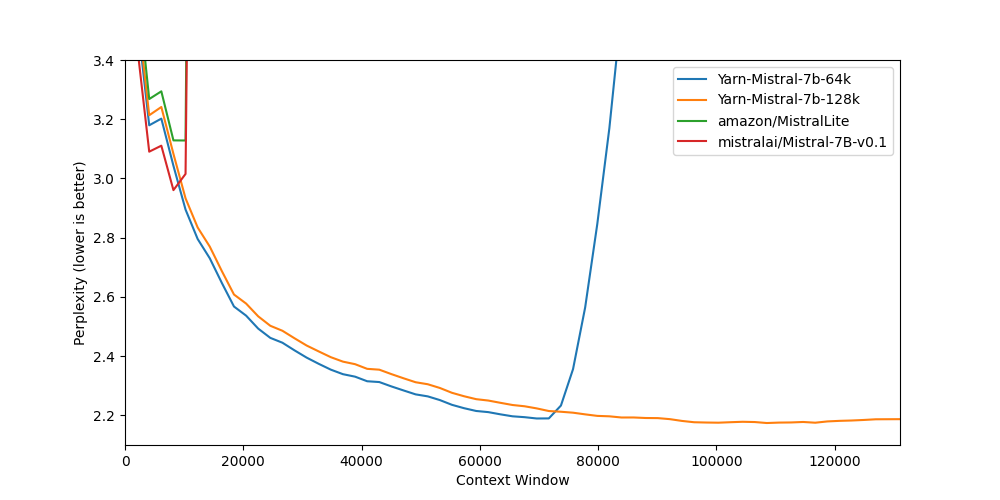
| Nous-Yarn-Mistral-7b-128k is a state-of-the-art language model for long context, further pretrained on long context data for 1500 steps using the YaRN extension method. | |
| It is an extension of [Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1) and supports a 128k token context window. | |
| To use, pass `trust_remote_code=True` when loading the model, for example | |
| ```python | |
| model = AutoModelForCausalLM.from_pretrained("NousResearch/Yarn-Mistral-7b-128k", | |
| use_flash_attention_2=True, | |
| torch_dtype=torch.bfloat16, | |
| device_map="auto", | |
| trust_remote_code=True) | |
| ``` | |
| In addition you will need to use the latest version of `transformers` (until 4.35 comes out) | |
| ```sh | |
| pip install git+https://github.com/huggingface/transformers | |
| ``` | |
| ## Benchmarks | |
| Long context benchmarks: | |
| | Model | Context Window | 8k PPL | 16k PPL | 32k PPL | 64k PPL | 128k PPL | | |
| |-------|---------------:|------:|----------:|-----:|-----:|------------:| | |
| | [Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1) | 8k | 2.96 | - | - | - | - | | |
| | [Yarn-Mistral-7b-64k](https://huggingface.co/NousResearch/Yarn-Mistral-7b-64k) | 64k | 3.04 | 2.65 | 2.44 | 2.20 | - | | |
| | [Yarn-Mistral-7b-128k](https://huggingface.co/NousResearch/Yarn-Mistral-7b-128k) | 128k | 3.08 | 2.68 | 2.47 | 2.24 | 2.19 | | |
| Short context benchmarks showing that quality degradation is minimal: | |
| | Model | Context Window | ARC-c | Hellaswag | MMLU | Truthful QA | | |
| |-------|---------------:|------:|----------:|-----:|------------:| | |
| | [Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1) | 8k | 59.98 | 83.31 | 64.16 | 42.15 | | |
| | [Yarn-Mistral-7b-64k](https://huggingface.co/NousResearch/Yarn-Mistral-7b-64k) | 64k | 59.38 | 81.21 | 61.32 | 42.50 | | |
| | [Yarn-Mistral-7b-128k](https://huggingface.co/NousResearch/Yarn-Mistral-7b-128k) | 128k | 58.87 | 80.58 | 60.64 | 42.46 | | |
| ## Collaborators | |
| - [bloc97](https://github.com/bloc97): Methods, paper and evals | |
| - [@theemozilla](https://twitter.com/theemozilla): Methods, paper, model training, and evals | |
| - [@EnricoShippole](https://twitter.com/EnricoShippole): Model training | |
| - [honglu2875](https://github.com/honglu2875): Paper and evals | |
| The authors would like to thank LAION AI for their support of compute for this model. | |
| It was trained on the [JUWELS](https://www.fz-juelich.de/en/ias/jsc/systems/supercomputers/juwels) supercomputer. |